← LEARN LLM · RESEARCH INDEX
1 ENTRY
RAG
1 post tagged RAG. All topics
2026
1 note-
01
You Don't Need Long Context: Compaction, Selective Reading, and Semantic State Space Models
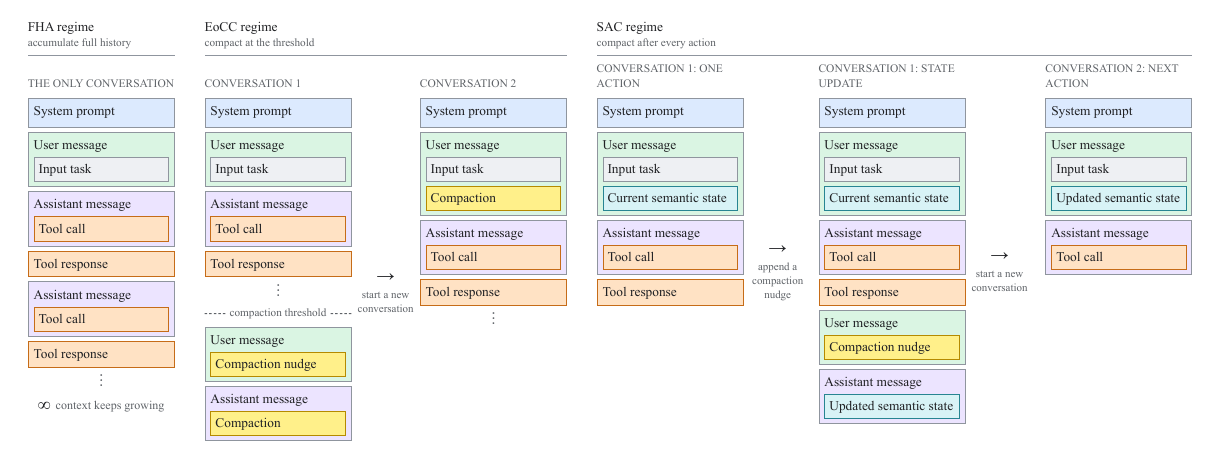
NVIDIA researchers evaluate whether frontier language models require 200K–1M token contexts (arXiv:2611.05306). Serving at 16K instead of 256K boosts H100 decode throughput by 3.6x–7x, End-of-Conversation Compaction and Selective Reading match or beat full-context baselines across 13 benchmarks, and Single-Action Compaction solves 70.2%–82.4% of SWE-bench Verified at a 7K–8K median peak context.