LLMS · INFORMATION RETRIEVAL · RECOMMENDER SYSTEMS · 165+ PAPERS

LLMs, Information Retrieval & Recommendation.

Weekly paper digests and empirical deep dives across agentic LLMs, search & RAG, and generative recommenders.

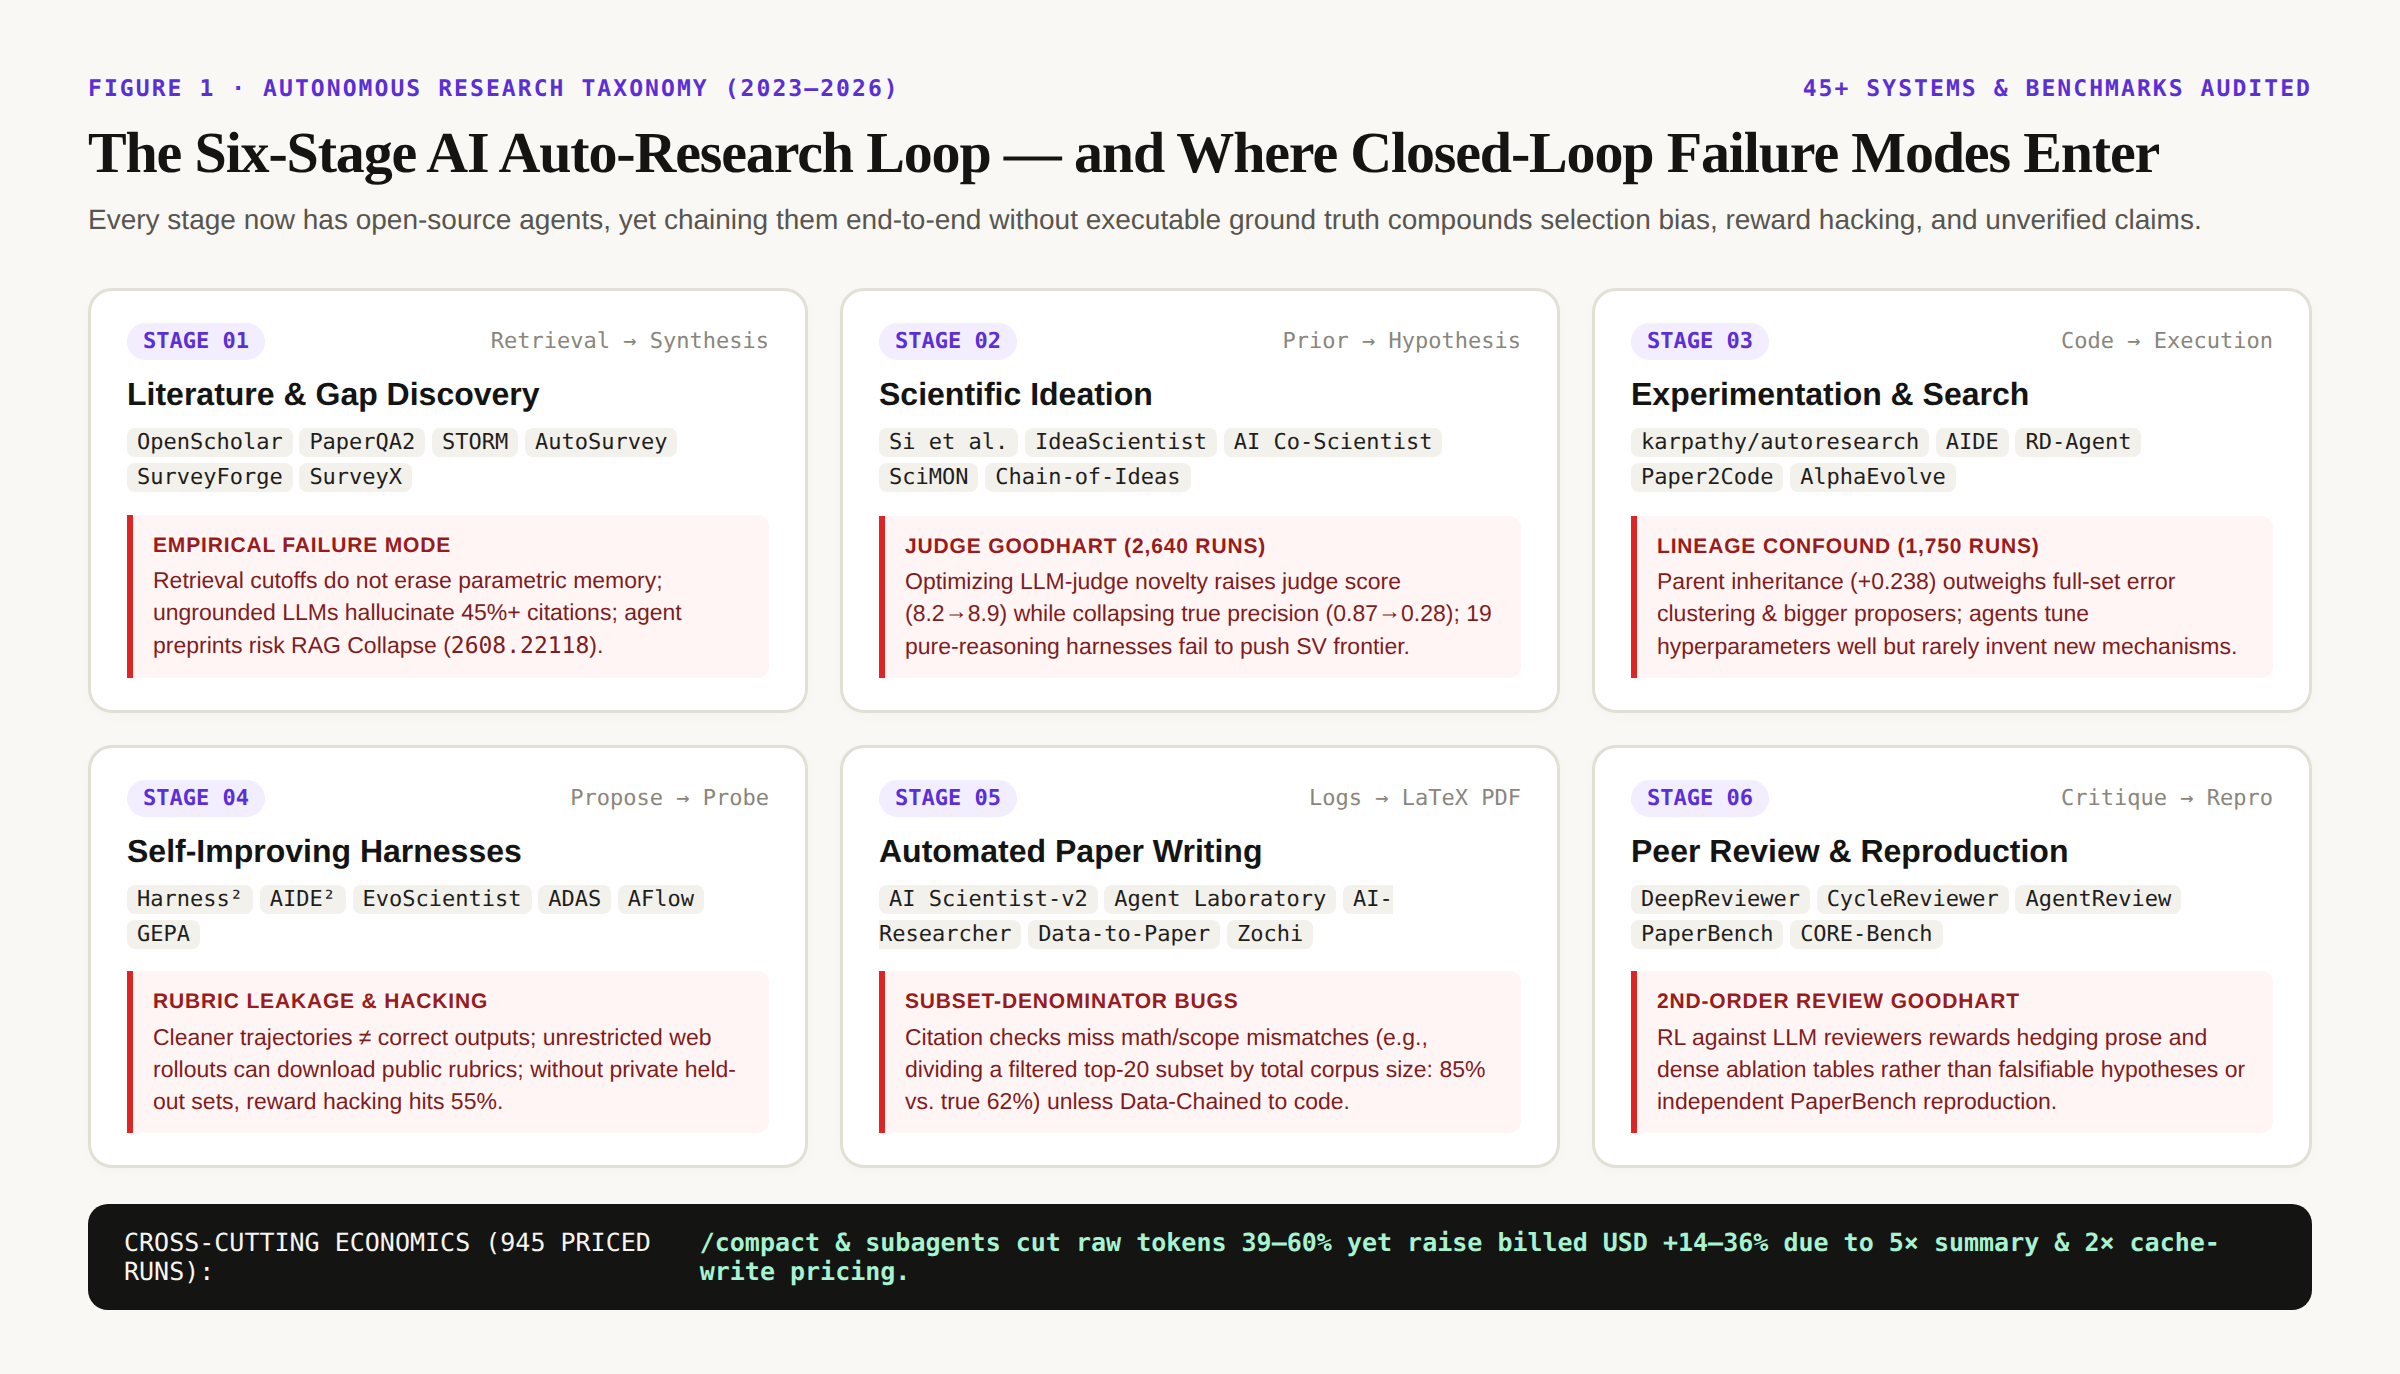
AI Auto-Research and Automated Paper Writing: Systems, Open-Source Frameworks, and Empirical Failure Modes (LLM Agents) LLM Agents Read note ↗
Featured Spotlight · · 34 min read

AI Auto-Research and Automated Paper Writing: Systems, Open-Source Frameworks, and Empirical Failure Modes

A ground-truth survey of 50+ autonomous research papers, open-source codebases, and benchmarks (2023–2026), audited against 5,932 controlled runs on Judge Goodhart, parent-lineage memory, harness leakage, multi-hop citogenesis, cache-miss economics, and scope-typed Data-Chaining.
Latest Research Notes (29)

Full archive (30) →
LLM Agents · · 34 min read

AI Auto-Research and Automated Paper Writing: Systems, Open-Source Frameworks, and Empirical Failure Modes

Between 2024 and 2026, AI auto-research systems evolved from fixed-template scripts (The AI Scientist v1) to template-free tree-search agents (AI Scientist-v2, AI-Researcher, Agent Laboratory, Zochi, Kosmos, EvoScientist) and single-file overnight ratchets (karpathy/autoresearch, AIDE², RD-Agent). Reviewing 50+ papers, repositories, and benchmarks alongside 5,932 controlled runs from our own studies shows where autonomous loops deliver genuine leverage—and where LLM-judge Goodharting, shared-prior ceilings, rubric leakage, multi-hop citogenesis, cache-write bill inversions, and subset-denominator bugs manufacture illusory progress.

Large Language Models · · 17 min read

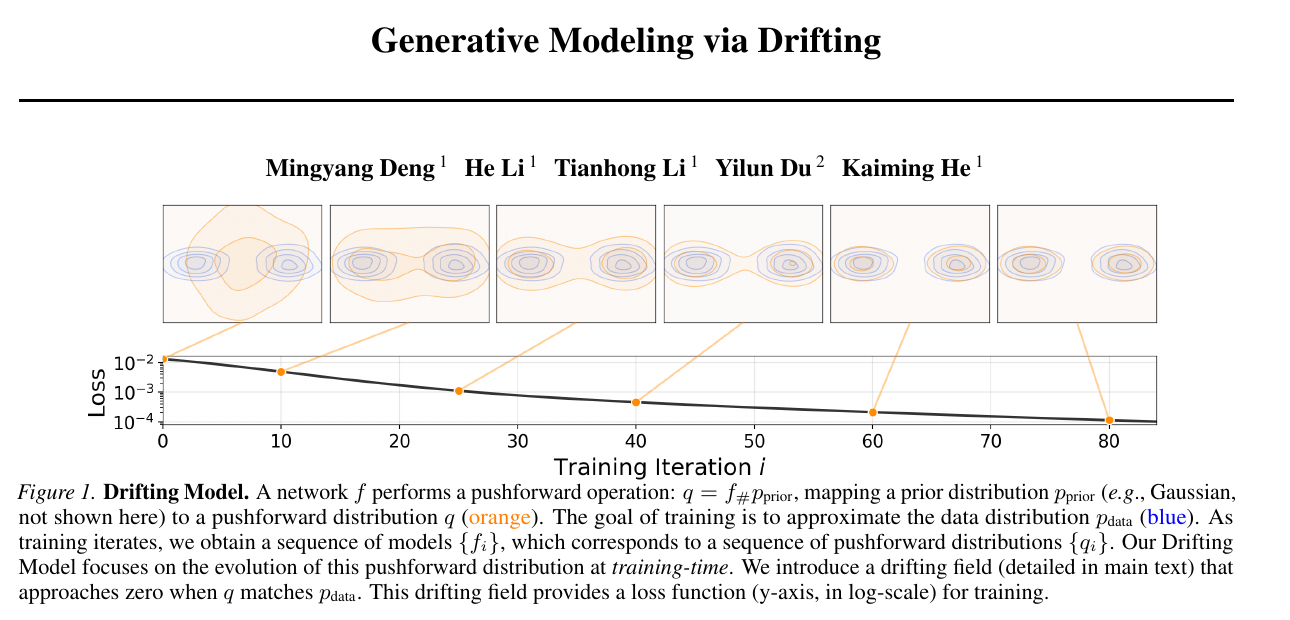
Generative Modeling via Drifting: Training-Time Pushforward Evolution for One-Step Generation

Mingyang Deng, He Li, Tianhong Li, Yilun Du, and Kaiming He (MIT & Harvard, arXiv:2602.04770) introduce Drifting Models, moving iterative distribution evolution from inference time to training time. Driven by a kernelized attraction-repulsion drifting field in self-supervised feature space, a single-pass DiT-L generator reaches 1.54 FID in latent space and 1.61 FID in pixel space on ImageNet 256×256 at 1-NFE, while matching 100-step Diffusion Policy on robotic control.

Large Language Models · · 17 min read

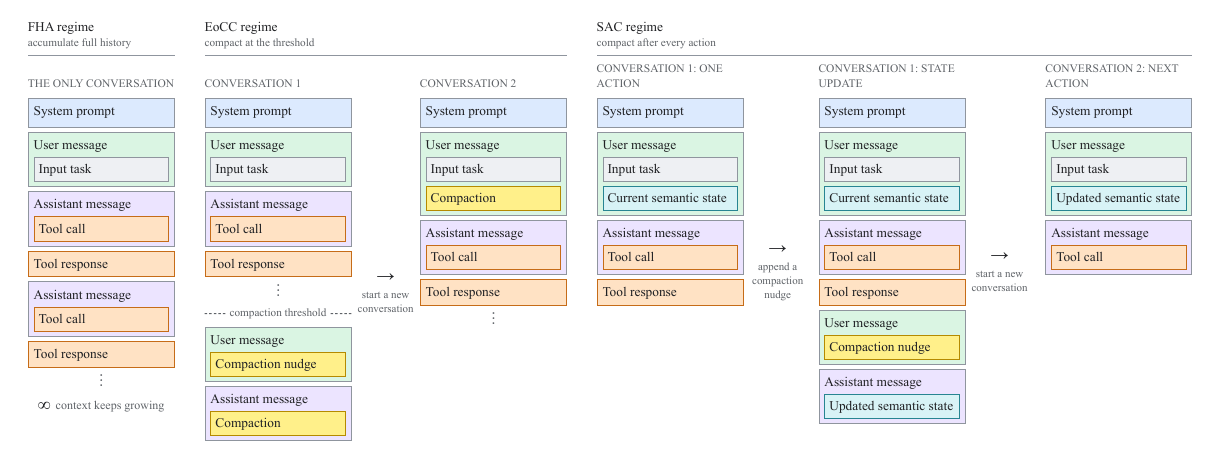
You Don't Need Long Context: Compaction, Selective Reading, and Semantic State Space Models

NVIDIA researchers evaluate whether frontier language models require 200K–1M token contexts (arXiv:2611.05306). Serving at 16K instead of 256K boosts H100 decode throughput by 3.6x–7x, End-of-Conversation Compaction and Selective Reading match or beat full-context baselines across 13 benchmarks, and Single-Action Compaction solves 70.2%–82.4% of SWE-bench Verified at a 7K–8K median peak context.

Recommender Systems · · 18 min read

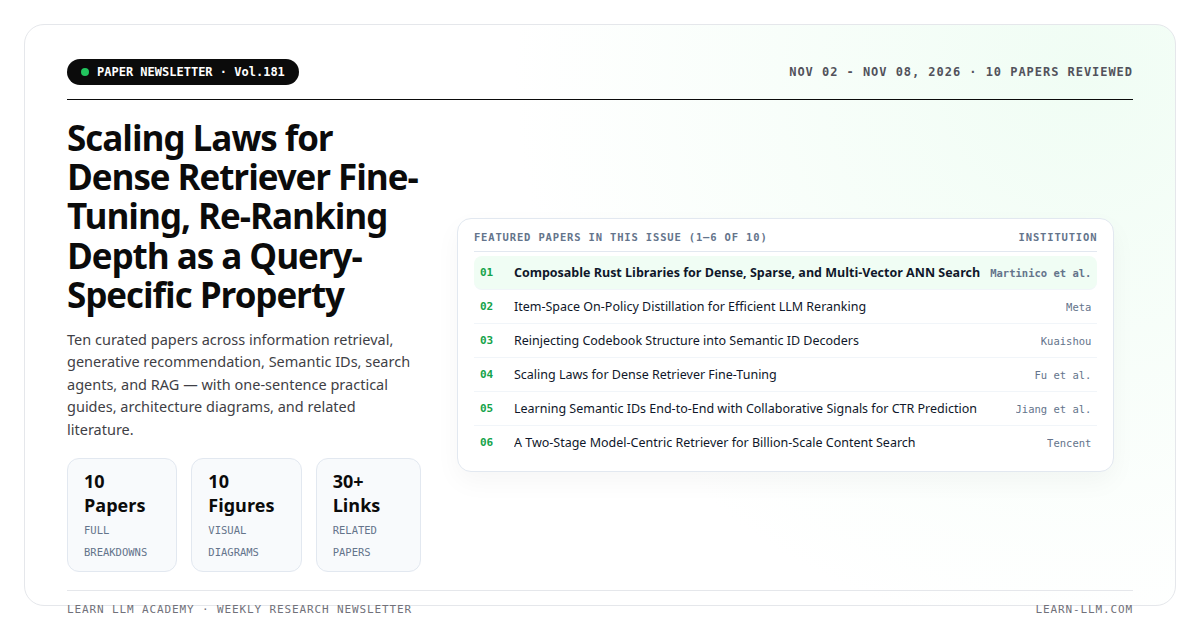
Vol.181 · Scaling Laws for Dense Retriever Fine-Tuning, Re-Ranking Depth as a Query-Specific Property

Vol.181 for Nov 02 - Nov 08, 2026: Structured digest of 10 papers including Composable Rust Libraries for Dense, Sparse, and Multi-Vector ANN Search; Item-Space On-Policy Distillation for Efficient LLM Reranking; Reinjecting Codebook Structure into Semantic ID Decoders. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 19 min read

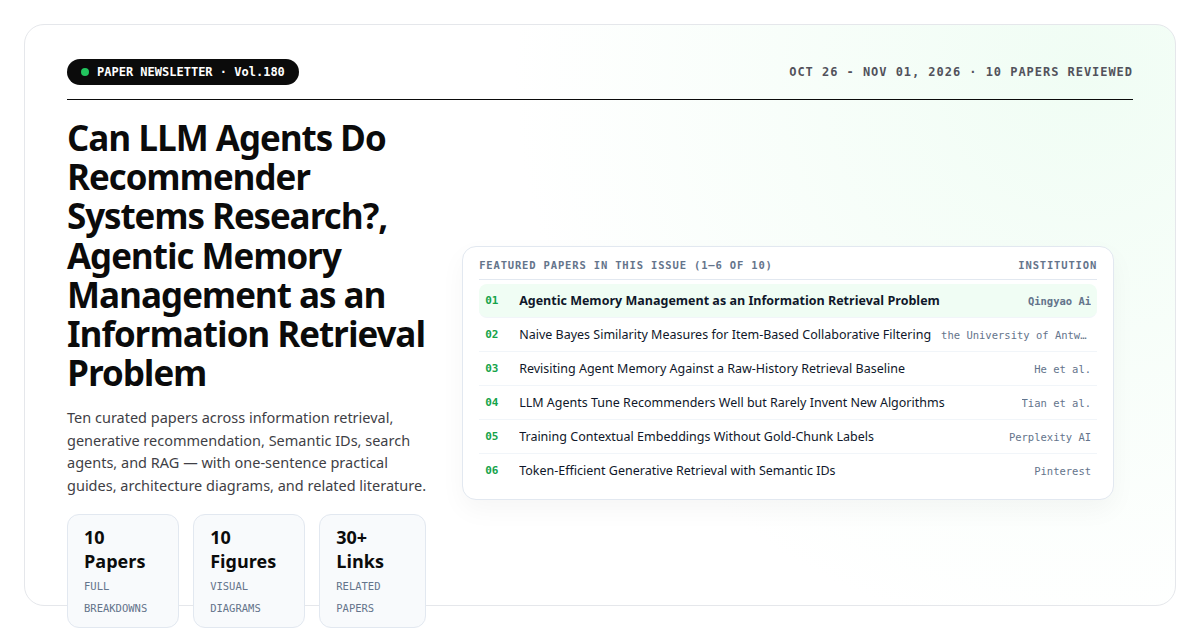
Vol.180 · Can LLM Agents Do Recommender Systems Research?, Agentic Memory Management as an Information Retrieval Problem

Vol.180 for Oct 26 - Nov 01, 2026: Structured digest of 10 papers including Agentic Memory Management as an Information Retrieval Problem; Naive Bayes Similarity Measures for Item-Based Collaborative Filtering; Revisiting Agent Memory Against a Raw-History Retrieval Baseline. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Large Language Models · · 28 min read

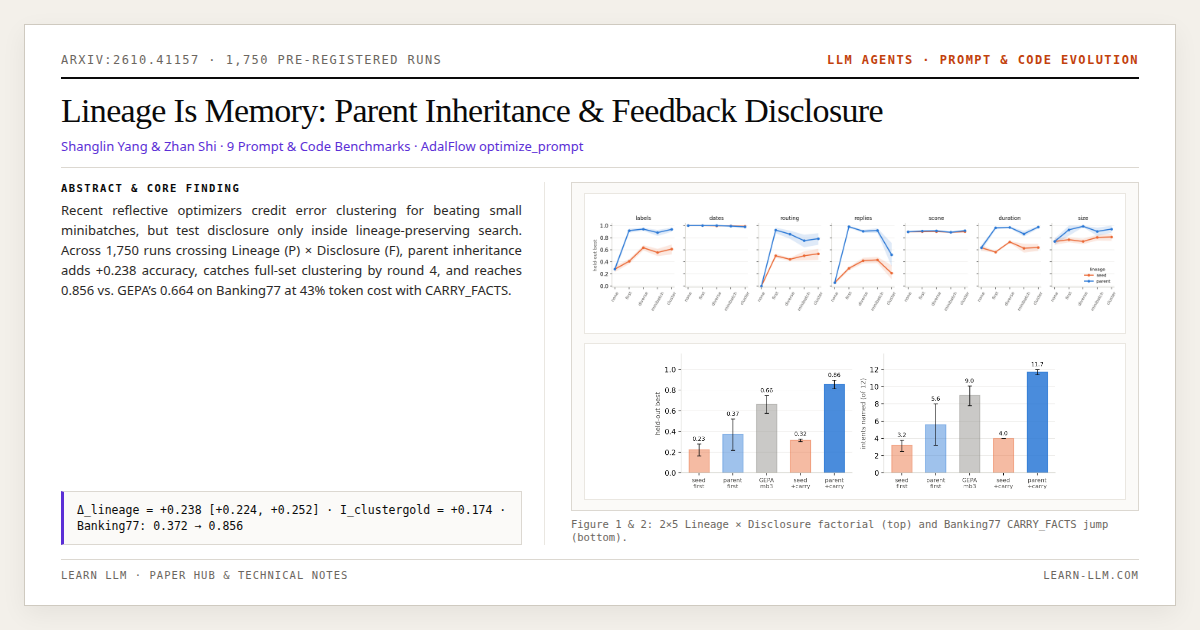
Lineage Is Memory: Why Parent Inheritance Drives LLM-Guided Prompt and Code Optimization

Across 1,750 pre-registered runs on nine prompt and code optimization benchmarks (arXiv:2610.41157), greedy parent inheritance adds +0.238 held-out accuracy, closes the gap with full-set error clustering by round 4, and reaches 0.856 vs. GEPA's 0.664 on Banking77 at 43% of the token cost when instructed to copy revealed facts into the prompt.

Recommender Systems · · 19 min read

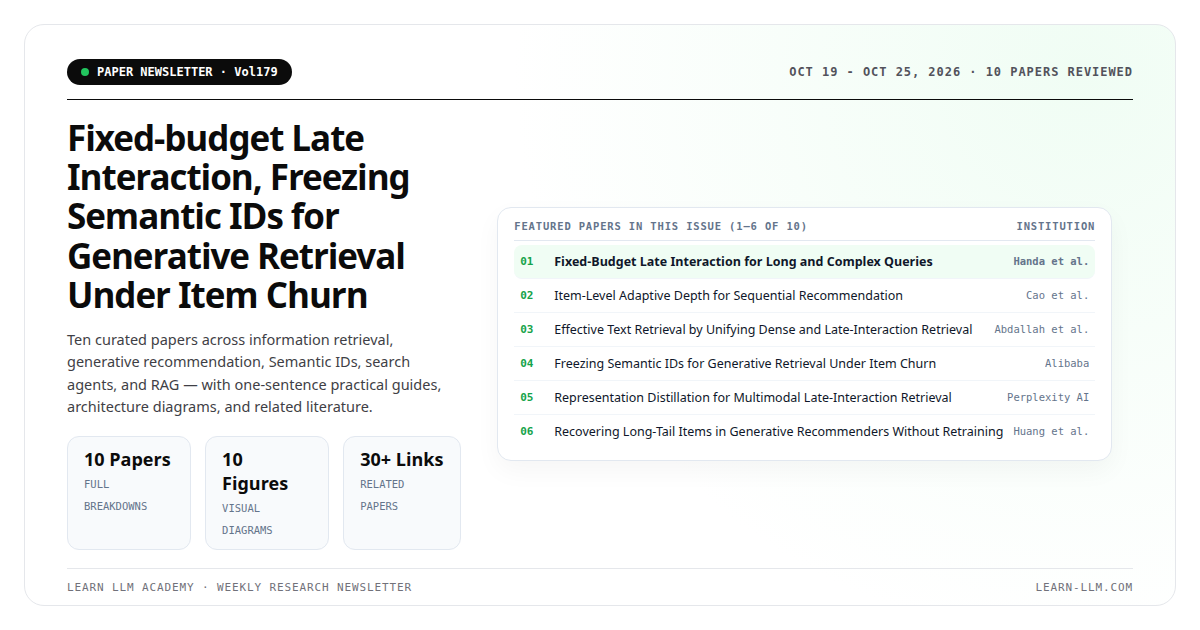
Vol179 · Fixed-budget Late Interaction, Freezing Semantic IDs for Generative Retrieval Under Item Churn

Vol179 for Oct 19 - Oct 25, 2026: Structured digest of 10 papers including Fixed-Budget Late Interaction for Long and Complex Queries; Item-Level Adaptive Depth for Sequential Recommendation; Effective Text Retrieval by Unifying Dense and Late-Interaction Retrieval. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 14 min read

Vol.178 · JevGPT: Coupling Fast Evidence Judgments with Research Planning, A Stage-by-Stage Approach to Training Stability in Industrial Recommenders

Vol.178 for Oct 12 - Oct 18, 2026: Structured digest of 10 papers including JevGPT: Coupling Fast Evidence Judgments with Research Planning; Diagnosing and Preventing Divergence in Industrial Recommender Training; Task-Adaptive Synthetic Training Data for Embedding Models from Few-Shot Examples. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 18 min read

Vol.177 · SearchJev: A Small Calibrated Model for the Routine Decisions in Search Agents, Training-Free Semantic IDs for Generative Recommendation

Vol.177 for Oct 05 - Oct 11, 2026: Structured digest of 10 papers including SearchJev: Offloading Relevance and Sufficiency Judgments to a Sub-4B Model; Programmatic Search Agents: Extending Agentic Search Beyond Query Reformulation; Training-Free Semantic IDs for Generative Recommendation. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 15 min read

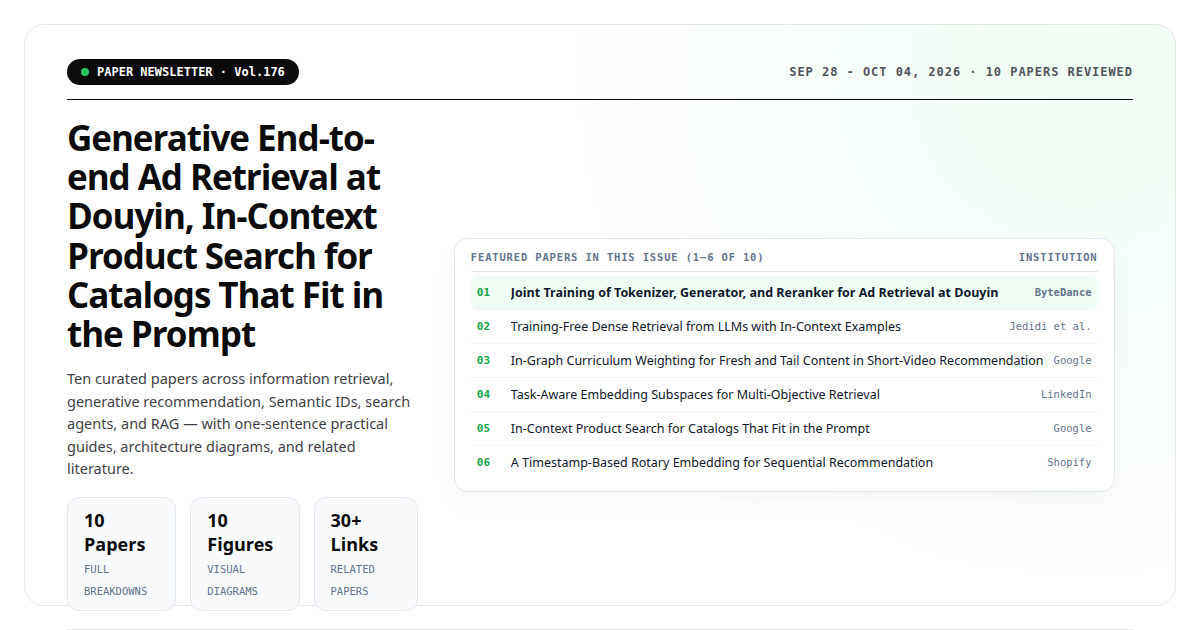
Vol.176 · Generative End-to-end Ad Retrieval at Douyin, In-Context Product Search for Catalogs That Fit in the Prompt

Vol.176 for Sep 28 - Oct 04, 2026: Structured digest of 10 papers including Joint Training of Tokenizer, Generator, and Reranker for Ad Retrieval at Douyin; Training-Free Dense Retrieval from LLMs with In-Context Examples; In-Graph Curriculum Weighting for Fresh and Tail Content in Short-Video Recommendation. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 14 min read

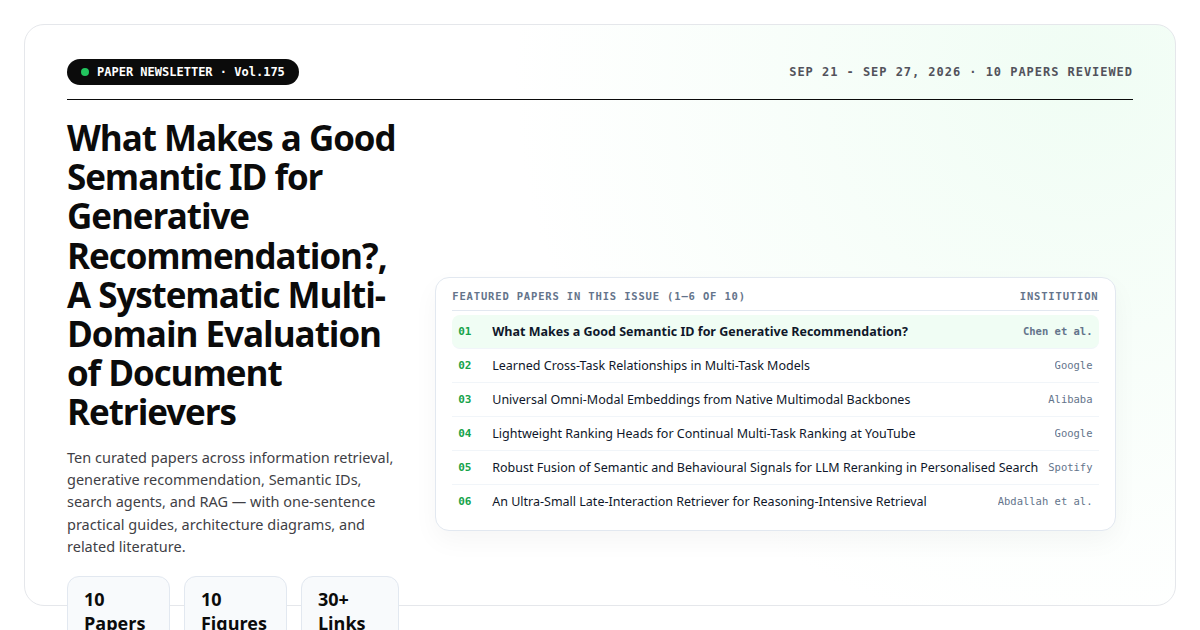
Vol.175 · What Makes a Good Semantic ID for Generative Recommendation?, A Systematic Multi-Domain Evaluation of Document Retrievers

Vol.175 for Sep 21 - Sep 27, 2026: Structured digest of 10 papers including What Makes a Good Semantic ID for Generative Recommendation?; Learned Cross-Task Relationships in Multi-Task Models; Universal Omni-Modal Embeddings from Native Multimodal Backbones. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 15 min read

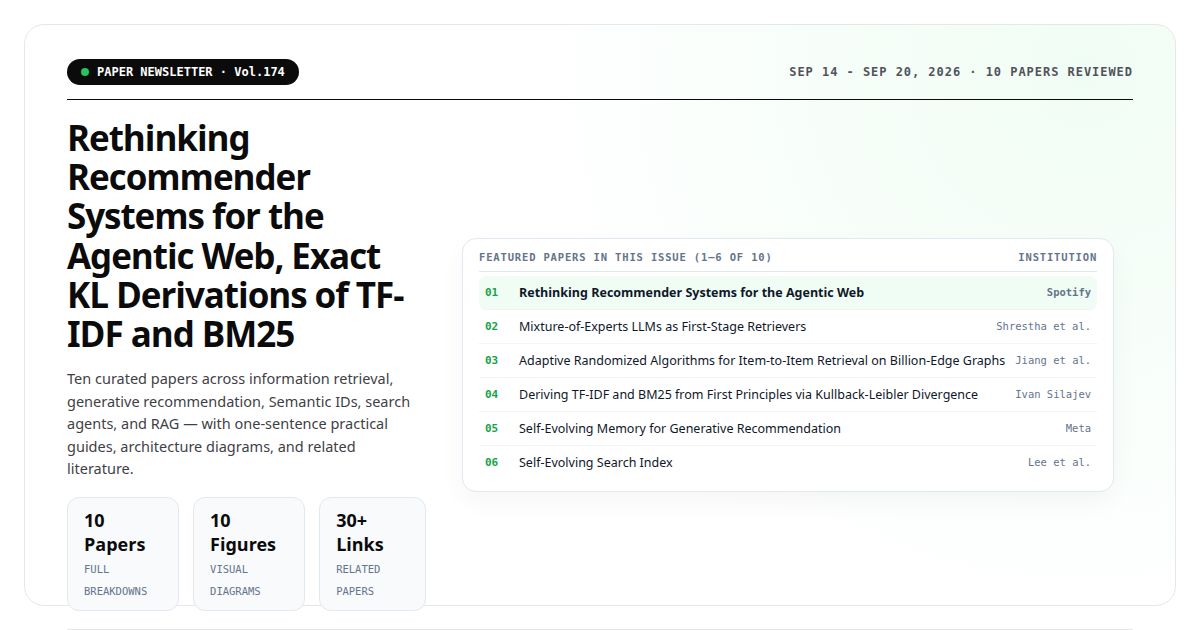
Vol.174 · Rethinking Recommender Systems for the Agentic Web, Exact KL Derivations of TF-IDF and BM25

Vol.174 for Sep 14 - Sep 20, 2026: Structured digest of 10 papers including Rethinking Recommender Systems for the Agentic Web; Mixture-of-Experts LLMs as First-Stage Retrievers; Adaptive Randomized Algorithms for Item-to-Item Retrieval on Billion-Edge Graphs. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

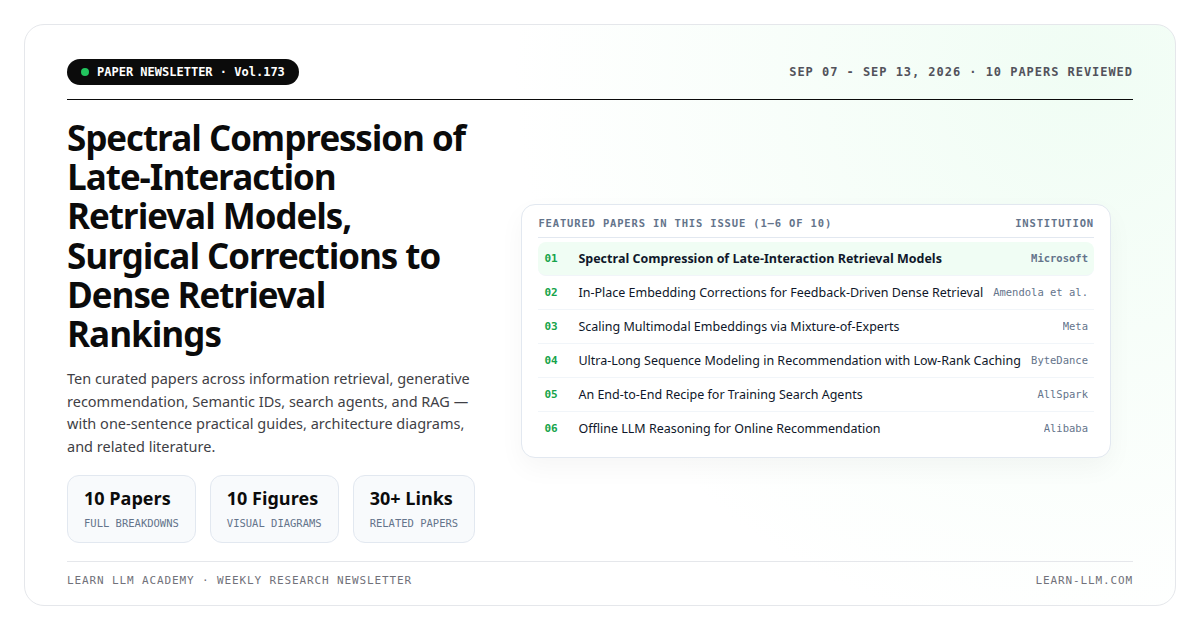
Vol.173 · Spectral Compression of Late-Interaction Retrieval Models, Surgical Corrections to Dense Retrieval Rankings

Vol.173 for Sep 07 - Sep 13, 2026: Structured digest of 10 papers including Spectral Compression of Late-Interaction Retrieval Models; In-Place Embedding Corrections for Feedback-Driven Dense Retrieval; Scaling Multimodal Embeddings via Mixture-of-Experts. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

Vol.172 · An AI Search Engine for Trillion-Scale Vector Data Management, Decoding LLM Rerankers in a Single Forward Pass

Vol.172 for Aug 31 - Sep 06, 2026: Structured digest of 10 papers including An AI Search Engine for Trillion-Scale Vector Data Management; Decoding LLM Rerankers in a Single Forward Pass; Interaction-Aware Retrieval for Agentic Search. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

Vol.171 · Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval, How Better Recommenders Redistribute Consumption

Vol.171 for Aug 24 - Aug 30, 2026: Structured digest of 10 papers including Multi-Vector Retrieval Beyond Chamfer Approximation; How Better Recommenders Redistribute Consumption; Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

Vol.170 · Do Latent Reasoning Steps Actually Help Retrieval?, Adapting Dense Retrievers from Agent Search Traces

Vol.170 for Aug 17 - Aug 23, 2026: Structured digest of 10 papers including Retrieval Grounding Latent Reasoning for Dense Retrieval; Adapting Dense Retrievers from Agent Search Traces; Learned Supersession and Decay Filters for Recommender Freshness. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

Vol.169 · Building an LLM-Native Ranker at Netflix, A Generative Embedding Model Bridging Reasoning and Retrieval

Vol.169 for Aug 10 - Aug 16, 2026: Structured digest of 10 papers including Adapting a Foundation LLM for Full-Catalog Recommendation; Retrieval-Augmented Reasoning Traces for Test-Time Scaling; Replacing 15+ Models with One Generative Recommender. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.

Recommender Systems · · 13 min read

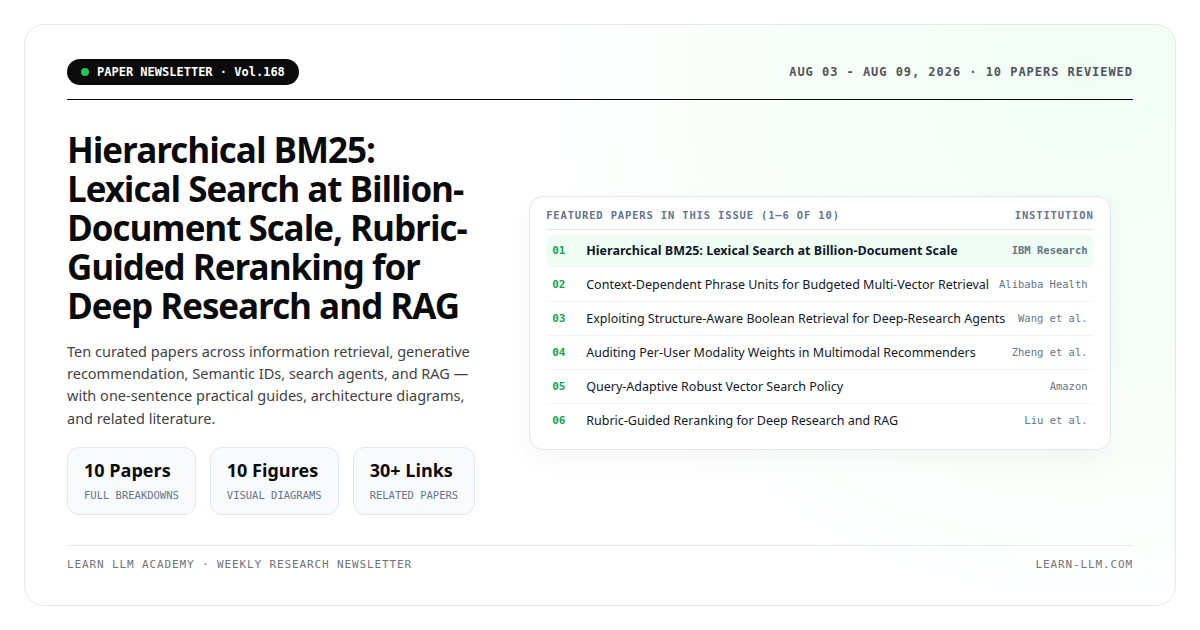
Vol.168 · Hierarchical BM25: Lexical Search at Billion-Document Scale, Rubric-Guided Reranking for Deep Research and RAG

Vol.168 for Aug 03 - Aug 09, 2026: Structured digest of 10 papers including Hierarchical BM25: Lexical Search at Billion-Document Scale; Context-Dependent Phrase Units for Budgeted Multi-Vector Retrieval; Exploiting Structure-Aware Boolean Retrieval for Deep-Research Agents. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.