Vol.171 · Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval, How Better Recommenders Redistribute Consumption
Vol.171 for Aug 24 - Aug 30, 2026: Structured digest of 10 papers including Multi-Vector Retrieval Beyond Chamfer Approximation; How Better Recommenders Redistribute Consumption; Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval. Includes a quick-reference paper list, one-sentence practical use cases, figure screenshots, and related literature.
Paper List & One-Sentence Practical Guide
This issue (Vol.171 for Aug 24 - Aug 30, 2026) covers 10 papers across information retrieval, generative recommendation, Semantic IDs, LLM reranking, and agentic search. Start with the quick-reference list below to see what each paper is useful for and which related papers to read alongside it, or jump directly to any paper's detailed section and architecture screenshot.
Multi-Vector Retrieval Beyond Chamfer Approximation (from Microsoft Research) — Paper
- What it's useful for: Use this framework (from Microsoft Research) to cut the memory footprint, CPU–GPU transfer overhead, and MaxSim scoring latency of ColBERT-style multi-vector retrievers while retaining fine-grained token matching.
- Related papers: ColBERTv2: Effective and Efficient Retrieval via Lightweight Late Interaction · Knowing When to Intervene: RL, Search Agents, and RAG · Also in this issue: #3 Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval
How Better Recommenders Redistribute Consumption (from Netflix) — Paper
- What it's useful for: Use this architecture (from Netflix) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #4 A Dynamic Single-Level Semantic Codebook for Generative Recommendation
Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval (from the University of Massachusetts) — Paper
- What it's useful for: Use this framework (from the University of Massachusetts) to cut the memory footprint, CPU–GPU transfer overhead, and MaxSim scoring latency of ColBERT-style multi-vector retrievers while retaining fine-grained token matching.
- Related papers: ColBERTv2: Effective and Efficient Retrieval via Lightweight Late Interaction · Knowing When to Intervene: RL, Search Agents, and RAG · Also in this issue: #1 Multi-Vector Retrieval Beyond Chamfer Approximation
A Dynamic Single-Level Semantic Codebook for Generative Recommendation (from Kuaishou) — Paper
- What it's useful for: Use this method (from Kuaishou) to construct and decode discrete Semantic IDs that preserve collaborative and semantic item topology without codebook collapse or item-churn drift.
- Related papers: TIGER: Recommender Systems with Generative Retrieval · A Semantic Tokenizer Cannot Be Judged Without Its Decoder (FLASH) · Also in this issue: #2 How Better Recommenders Redistribute Consumption
Ingest-Time Semantic Compilation for RAG (from Wild et al.) — Paper
- What it's useful for: Use this architecture (from Wild et al.) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #2 How Better Recommenders Redistribute Consumption
Test-Time Scaling for Multi-Turn Search Agents via Retrieval Grounding (from Kook et al.) — Paper
- What it's useful for: Use this agentic search recipe (from Kook et al.) to train or control multi-step research agents with grounded rewards, fast sufficiency judgments, and programmatic evidence filtering.
- Related papers: Search Agents Need Better Decision Boundaries, Not Just Bigger Models · Knowing When to Intervene: Six Papers on RL, Search Agents, and RAG · Also in this issue: #7 Measuring Retrieval Robustness to Non-Relevant Document Addition
Measuring Retrieval Robustness to Non-Relevant Document Addition (from the University of Glasgow) — Paper
- What it's useful for: Use this architecture (from the University of Glasgow) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #2 How Better Recommenders Redistribute Consumption
Query-Adaptive Embedding Width for Dense Retrieval (from the University of Washington) — Paper
- What it's useful for: Use this architecture (from the University of Washington) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #2 How Better Recommenders Redistribute Consumption
A Multimodal Embedding Family for Text, Image, Video, and Visual Documents (from Tencent) — Paper
- What it's useful for: Use this architecture (from Tencent) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #2 How Better Recommenders Redistribute Consumption
Mixture-of-Experts Encoders for High-Throughput Text Embeddings (from Kolodin et al.) — Paper
- What it's useful for: Use this architecture (from Kolodin et al.) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
- Related papers: What a Recommender Can Reach, Remember, and Afford · When Should a Personal Agent Override Your Recommender? · Also in this issue: #2 How Better Recommenders Redistribute Consumption
Detailed Paper Sections
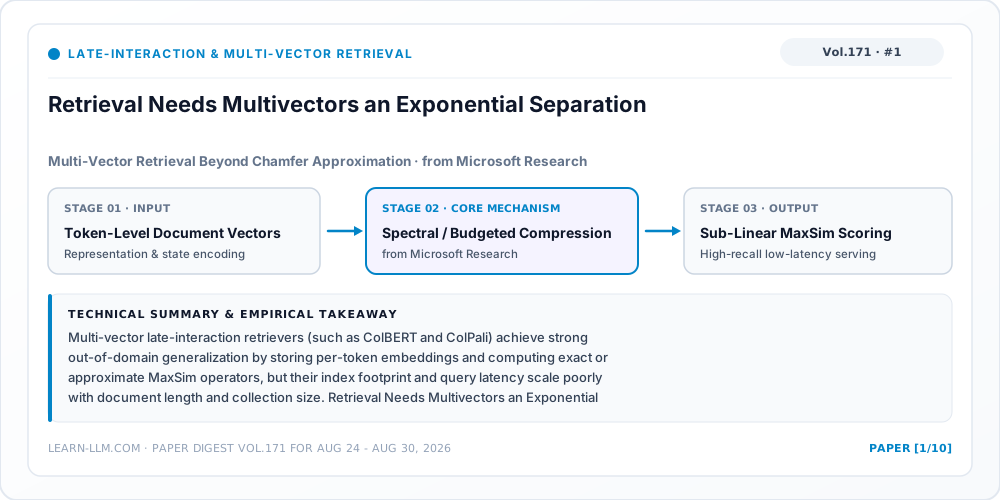
[1] Retrieval Needs Multivectors an Exponential Separation
- Newsletter Headline: Multi-Vector Retrieval Beyond Chamfer Approximation (from Microsoft Research)
- Links: arXiv Paper Search · Digest Section
- Research Area: Retrieval-Augmented Generation · Late-Interaction & Multi-Vector Retrieval
Main Content & Technical Findings
Multi-vector late-interaction retrievers (such as ColBERT and ColPali) achieve strong out-of-domain generalization by storing per-token embeddings and computing exact or approximate MaxSim operators, but their index footprint and query latency scale poorly with document length and collection size. Retrieval Needs Multivectors an Exponential Separation (from Microsoft Research) targets this bottleneck by compressing token subspaces, bounding interaction budgets, or co-scheduling GPU–CPU candidate pruning. Empirical benchmarks show that preserving dominant token directions or fixed-budget phrase units captures nearly all of full MaxSim relevance at a fraction of the storage and I/O cost.
Why It Matters in Production: Use this framework (from Microsoft Research) to cut the memory footprint, CPU–GPU transfer overhead, and MaxSim scoring latency of ColBERT-style multi-vector retrievers while retaining fine-grained token matching.
Related Papers
- ColBERTv2: Effective and Efficient Retrieval via Lightweight Late Interaction — Residual compression baseline for token-level late interaction.
- Knowing When to Intervene: RL, Search Agents, and RAG — LearnLLM digest on retrieval efficiency and adaptive pooling.
- #3 in this issue: Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval (from the University of Massachusetts) — Companion study in this newsletter.
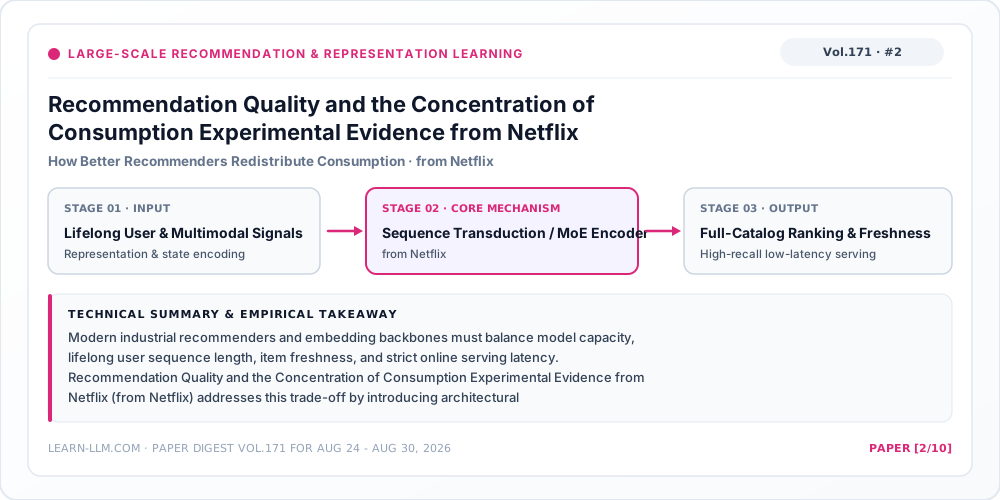
[2] Recommendation Quality and the Concentration of Consumption Experimental Evidence from Netflix
- Newsletter Headline: How Better Recommenders Redistribute Consumption (from Netflix)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. Recommendation Quality and the Concentration of Consumption Experimental Evidence from Netflix (from Netflix) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from Netflix) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #5 in this issue: Ingest-Time Semantic Compilation for RAG (from Wild et al.) — Companion study in this newsletter.
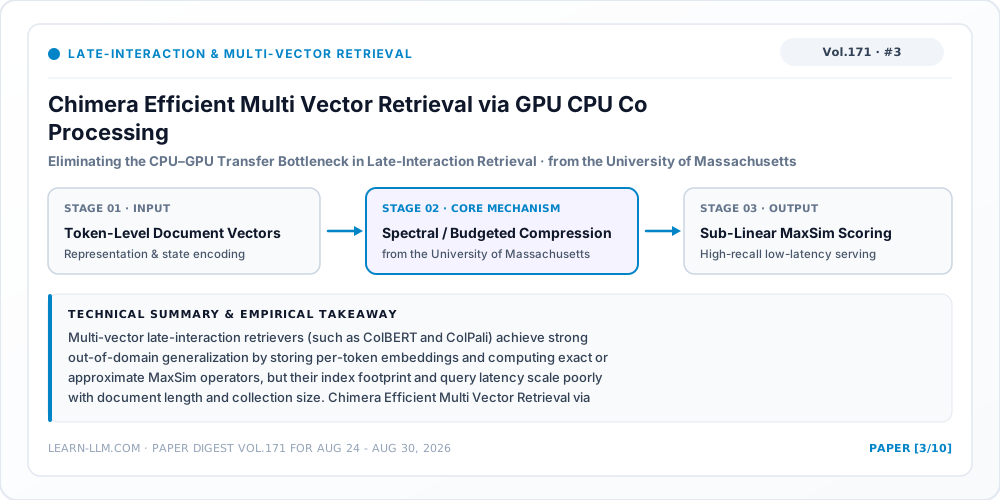
[3] Chimera Efficient Multi Vector Retrieval via GPU CPU Co Processing
- Newsletter Headline: Eliminating the CPU–GPU Transfer Bottleneck in Late-Interaction Retrieval (from the University of Massachusetts)
- Links: arXiv Paper Search · Digest Section
- Research Area: Retrieval-Augmented Generation · Late-Interaction & Multi-Vector Retrieval
Main Content & Technical Findings
Multi-vector late-interaction retrievers (such as ColBERT and ColPali) achieve strong out-of-domain generalization by storing per-token embeddings and computing exact or approximate MaxSim operators, but their index footprint and query latency scale poorly with document length and collection size. Chimera Efficient Multi Vector Retrieval via GPU CPU Co Processing (from the University of Massachusetts) targets this bottleneck by compressing token subspaces, bounding interaction budgets, or co-scheduling GPU–CPU candidate pruning. Empirical benchmarks show that preserving dominant token directions or fixed-budget phrase units captures nearly all of full MaxSim relevance at a fraction of the storage and I/O cost.
Why It Matters in Production: Use this framework (from the University of Massachusetts) to cut the memory footprint, CPU–GPU transfer overhead, and MaxSim scoring latency of ColBERT-style multi-vector retrievers while retaining fine-grained token matching.
Related Papers
- ColBERTv2: Effective and Efficient Retrieval via Lightweight Late Interaction — Residual compression baseline for token-level late interaction.
- Knowing When to Intervene: RL, Search Agents, and RAG — LearnLLM digest on retrieval efficiency and adaptive pooling.
- #1 in this issue: Multi-Vector Retrieval Beyond Chamfer Approximation (from Microsoft Research) — Companion study in this newsletter.
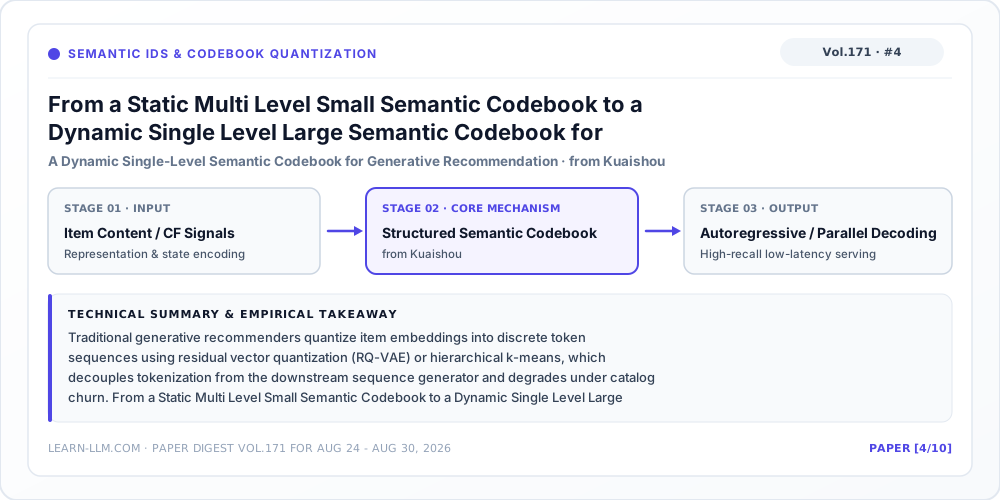
[4] From a Static Multi Level Small Semantic Codebook to a Dynamic Single Level Large Semantic Codebook for Generative Recommendation
- Newsletter Headline: A Dynamic Single-Level Semantic Codebook for Generative Recommendation (from Kuaishou)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Semantic IDs & Codebook Quantization
Main Content & Technical Findings
Traditional generative recommenders quantize item embeddings into discrete token sequences using residual vector quantization (RQ-VAE) or hierarchical k-means, which decouples tokenization from the downstream sequence generator and degrades under catalog churn. From a Static Multi Level Small Semantic Codebook to a Dynamic Single Level Large Semantic Codebook for Generative Recommendation (from Kuaishou) introduces a structure-aware tokenization and decoding recipe that aligns codebook assignments with collaborative user-item signals and decoding dynamics. By coupling code structure with sequence generation, the model prevents prefix collisions on popular items while preserving recall on long-tail and newly ingested catalog entries.
Why It Matters in Production: Use this method (from Kuaishou) to construct and decode discrete Semantic IDs that preserve collaborative and semantic item topology without codebook collapse or item-churn drift.
Related Papers
- TIGER: Recommender Systems with Generative Retrieval — Foundational RQ-VAE Semantic ID generative recommender.
- A Semantic Tokenizer Cannot Be Judged Without Its Decoder (FLASH) — LearnLLM deep dive on SimHash parallel decoding & alignment.
- Reachability Is Not Ranking: Finite Beams & Continuous Queries — LearnLLM analysis of beam reachability vs. ranking in SID models.
- #5 in this issue: Ingest-Time Semantic Compilation for RAG (from Wild et al.) — Companion study in this newsletter.
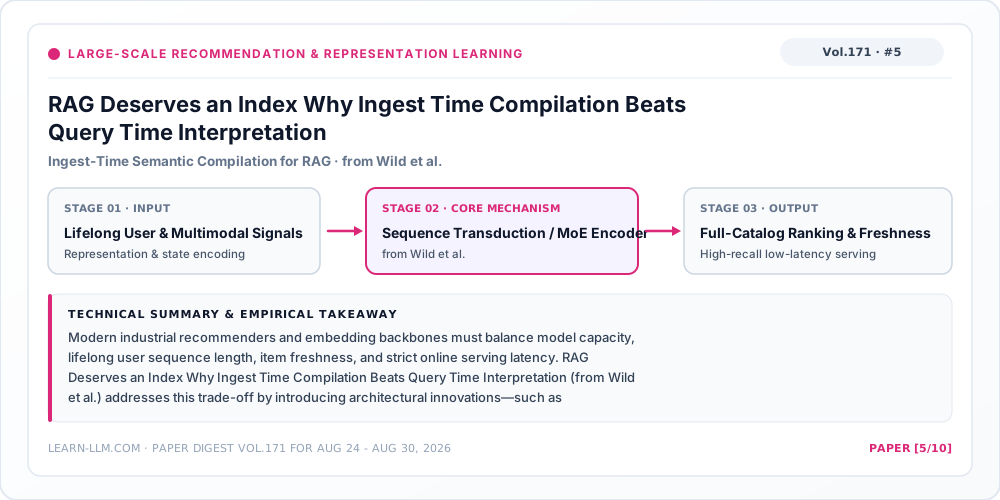
[5] RAG Deserves an Index Why Ingest Time Compilation Beats Query Time Interpretation
- Newsletter Headline: Ingest-Time Semantic Compilation for RAG (from Wild et al.)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. RAG Deserves an Index Why Ingest Time Compilation Beats Query Time Interpretation (from Wild et al.) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from Wild et al.) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #2 in this issue: How Better Recommenders Redistribute Consumption (from Netflix) — Companion study in this newsletter.
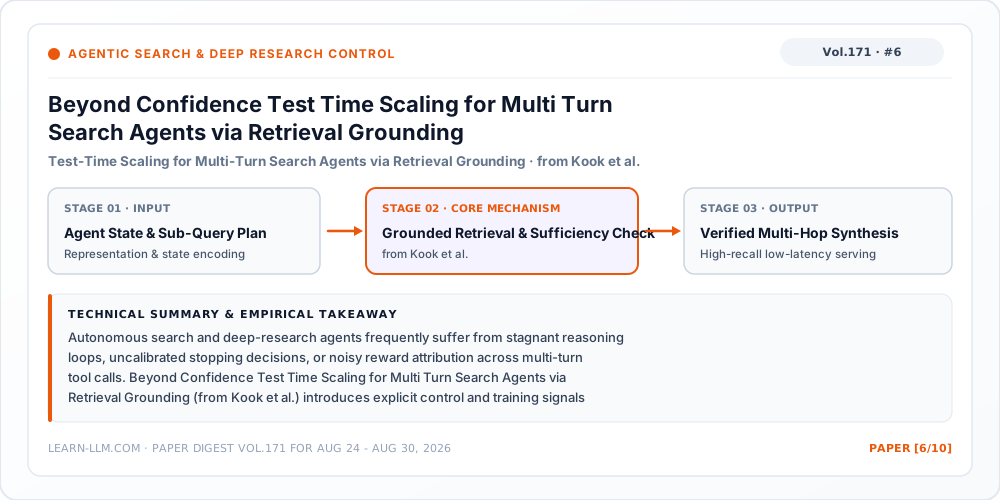
[6] Beyond Confidence Test Time Scaling for Multi Turn Search Agents via Retrieval Grounding
- Newsletter Headline: Test-Time Scaling for Multi-Turn Search Agents via Retrieval Grounding (from Kook et al.)
- Links: arXiv Paper Search · Digest Section
- Research Area: LLM Agents · Agentic Search & Deep Research Control
Main Content & Technical Findings
Autonomous search and deep-research agents frequently suffer from stagnant reasoning loops, uncalibrated stopping decisions, or noisy reward attribution across multi-turn tool calls. Beyond Confidence Test Time Scaling for Multi Turn Search Agents via Retrieval Grounding (from Kook et al.) introduces explicit control and training signals for agentic retrieval—coupling fast System-1 evidence judgments, programmatic workspace operations, or representation-grounded reinforcement learning rewards with multi-step query planning. Evaluations on multi-hop QA and web research benchmarks demonstrate higher evidence recall and lower token waste per solved question.
Why It Matters in Production: Use this agentic search recipe (from Kook et al.) to train or control multi-step research agents with grounded rewards, fast sufficiency judgments, and programmatic evidence filtering.
Related Papers
- Search Agents Need Better Decision Boundaries, Not Just Bigger Models — LearnLLM deep dive on SearchJev System-1/System-2 delegation.
- Knowing When to Intervene: Six Papers on RL, Search Agents, and RAG — LearnLLM digest on T-Search, Programmatic Search Agents, and AutoRAG.
- #7 in this issue: Measuring Retrieval Robustness to Non-Relevant Document Addition (from the University of Glasgow) — Companion study in this newsletter.
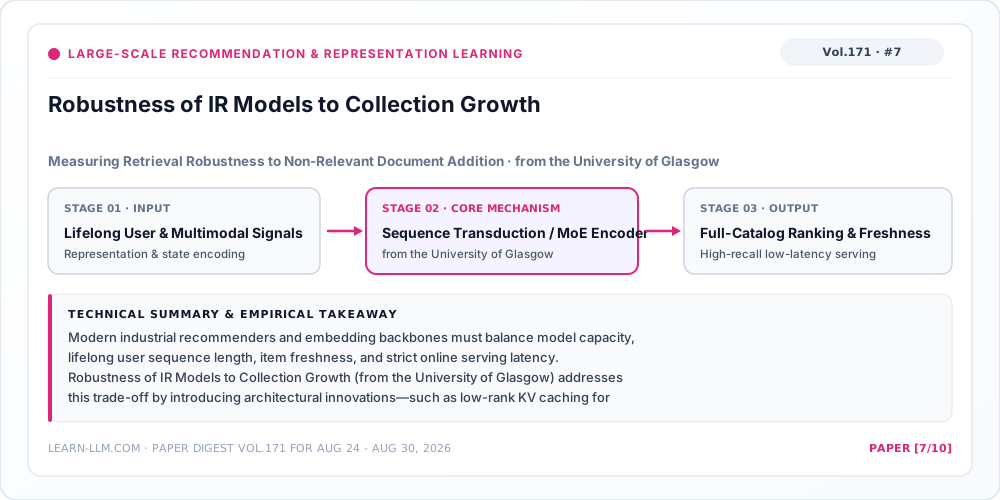
[7] Robustness of IR Models to Collection Growth
- Newsletter Headline: Measuring Retrieval Robustness to Non-Relevant Document Addition (from the University of Glasgow)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. Robustness of IR Models to Collection Growth (from the University of Glasgow) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from the University of Glasgow) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #2 in this issue: How Better Recommenders Redistribute Consumption (from Netflix) — Companion study in this newsletter.
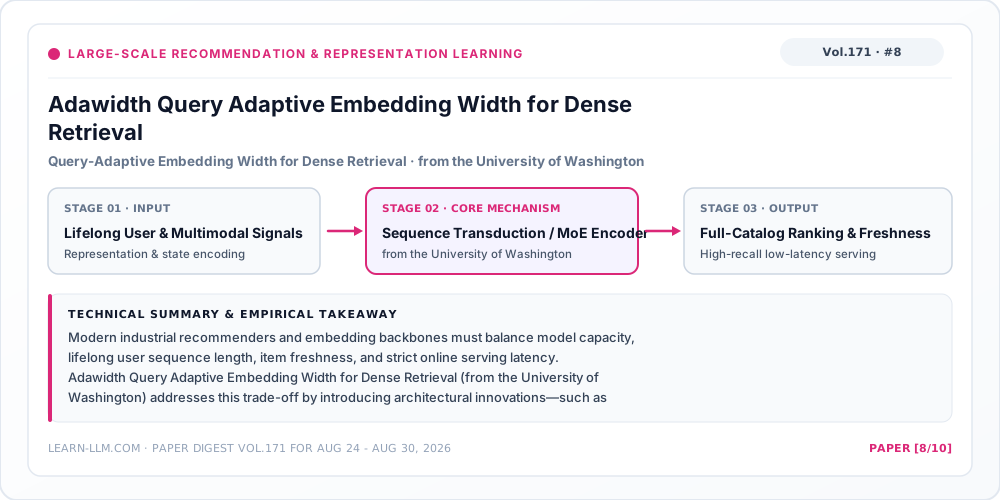
[8] Adawidth Query Adaptive Embedding Width for Dense Retrieval
- Newsletter Headline: Query-Adaptive Embedding Width for Dense Retrieval (from the University of Washington)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. Adawidth Query Adaptive Embedding Width for Dense Retrieval (from the University of Washington) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from the University of Washington) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #2 in this issue: How Better Recommenders Redistribute Consumption (from Netflix) — Companion study in this newsletter.
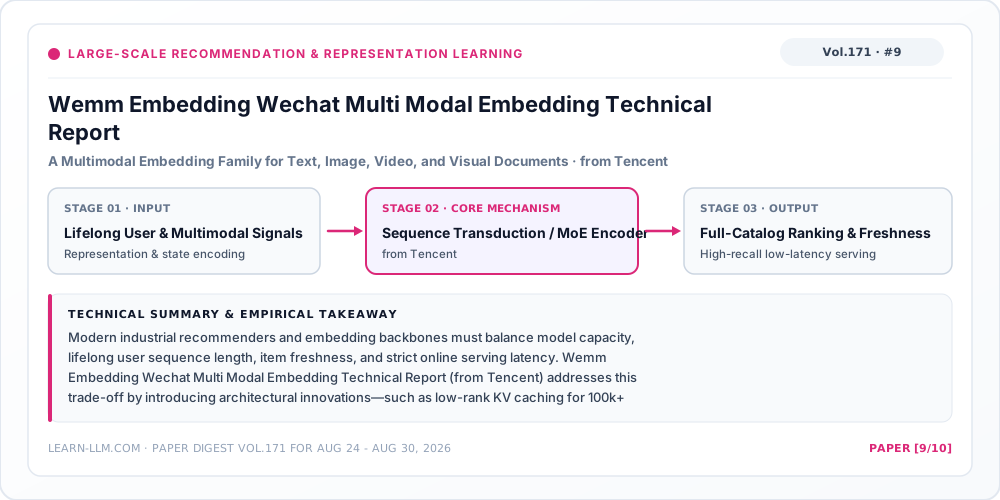
[9] Wemm Embedding Wechat Multi Modal Embedding Technical Report
- Newsletter Headline: A Multimodal Embedding Family for Text, Image, Video, and Visual Documents (from Tencent)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. Wemm Embedding Wechat Multi Modal Embedding Technical Report (from Tencent) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from Tencent) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #2 in this issue: How Better Recommenders Redistribute Consumption (from Netflix) — Companion study in this newsletter.
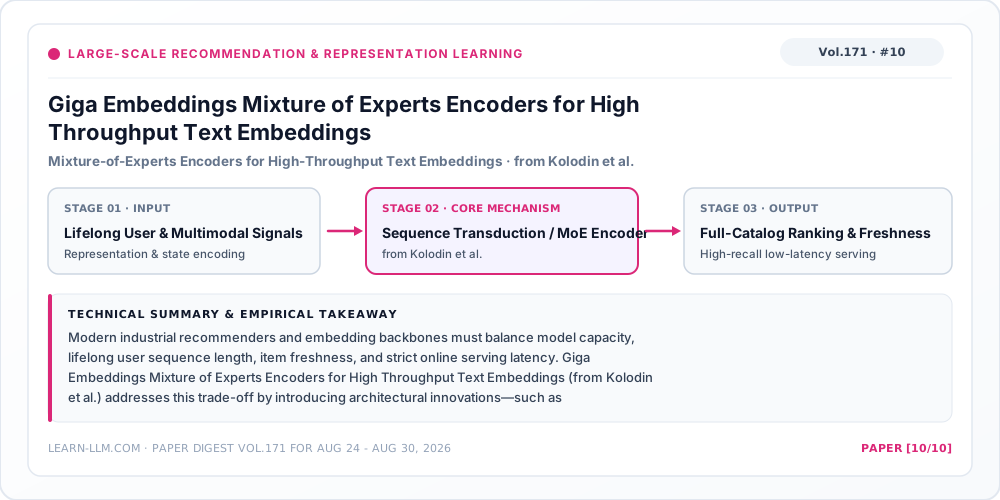
[10] Giga Embeddings Mixture of Experts Encoders for High Throughput Text Embeddings
- Newsletter Headline: Mixture-of-Experts Encoders for High-Throughput Text Embeddings (from Kolodin et al.)
- Links: arXiv Paper Search · Digest Section
- Research Area: Recommender Systems · Large-Scale Recommendation & Representation Learning
Main Content & Technical Findings
Modern industrial recommenders and embedding backbones must balance model capacity, lifelong user sequence length, item freshness, and strict online serving latency. Giga Embeddings Mixture of Experts Encoders for High Throughput Text Embeddings (from Kolodin et al.) addresses this trade-off by introducing architectural innovations—such as low-rank KV caching for 100k+ sequences, decoupled temporal encodings, supersession/decay freshness filters, or Mixture-of-Experts (MoE) representation backbones. Offline and production experiments confirm substantial gains in ranking accuracy, long-tail item coverage, and training/serving efficiency.
Why It Matters in Production: Use this architecture (from Kolodin et al.) to scale industrial recommendation and multimodal representation learning across long user histories, fresh/tail items, and multi-task serving constraints.
Related Papers
- What a Recommender Can Reach, Remember, and Afford — LearnLLM 7-paper synthesis on recommender reach, memory, and compute.
- When Should a Personal Agent Override Your Recommender? — LearnLLM review of value-floored RL alignment in recommendation.
- #2 in this issue: How Better Recommenders Redistribute Consumption (from Netflix) — Companion study in this newsletter.